Intro
Out of all the hyperscalers, AWS has the most database products. There's DynamoDB, RDS, ElastiCache, DocumentDB, Neptune, MemoryDB and the list goes on. One of the more popular offerings is Amazon Aurora. The confusing part is that there are multiple database offerings with Aurora in the name.
In fact, there are four (or you could argue three) offerings under the Amazon Aurora umbrella:
That's a lot! Why did they name them all Aurora? Why did they create DSQL when they already had limitless? Do they just love Postgres? I read the Aurora DSQL and Aurora Limitless research papers to hopefully answer these questions. I'll be focusing more on the differences in their architecture and design choices rather than their differences to an application developer. I am databasemaxxing after all.
Aurora MySQL/PostgreSQL
This is the classic Aurora offering and the first in the Aurora series. If you're familiar with AlloyDB, HorizonDB, or Neon, then you can think of it as something similar to those systems. The basic idea is that your Postgres/MySQL database doesn't live on a single machine. Aurora disaggregates compute and storage (basically Query Processor and Storage engine are separated). There is a single writer compute instance and you can add multiple read replicas, which are all backed by the same distributed storage layer.
This animation shows the flow for both read and write paths. Writes pass through a dedicated writer instance and reads can pass through any of the read instances (these can be scaled up/out).
The writer sends redo/WAL records to the distributed storage layer as changes occur. To commit a transaction, Aurora waits for the required storage quorum (4/6 storage copies ack the write) before acknowledging the commit. The storage layer of this system is replicated across three different AZs with six copies of the data across the AZs, so it is fairly fault-tolerant.
The single writer is the biggest limitation of classic Aurora. The single writer bottlenecks the write throughput of this system. You have the option to vertically scale your writer, but at some point, the vertical scaling won't be able to handle all your writes. At which point, you want to horizontally scale your writer. That leads us to Aurora Limitless.
Aurora Limitless
The folks at Amazon noticed the bottlenecks of classic Aurora and wanted to tackle them in a new system called Aurora Limitless (which we find out has its own limits). Aurora Limitless builds on top of a lot of the same ideas that classic Aurora had. Instead of having a single writer responsible for the whole DB, Aurora Limitless introduces routers and shards. Routers accept SQL queries from clients, plan and coordinate queries and forward requests to the relevant shards. Each shard is a Postgres compute instance responsible for a subset of the data. Aurora Limitless uses hash-based partitioning across these shards and the underlying data is still persisted in Aurora's distributed storage.
If a query touches only one shard, then the router can send the work directly there. Otherwise, for multi-shard writes, the router uses 2PC to coordinate work across all the shards that a transaction touches. The 2PC protocol to coordinate a commit across multiple shards is super interesting, but I won't dive into that here. If you're curious look at page 180 in the Aurora Limitless paper.
The last component is a control plane that manages the life cycle of the shards, monitors the health of all the routers/shards, handles auto-scaling, etc.
In this animation, the client issues a read query to router 3. Router 3 then uses its hash function on the dog_ids + routing metadata to understand which shard each of them belongs to. The router then sends the reads to those shards, combines their results and returns the result to the client.
You might be asking, "but what if one shard gets a majority of the requests?" That's where shard splitting comes in. Either the customer or the control plane notices that one of the shards needs more capacity and initiates a shard split. If a shard is already overloaded, the last thing that you want to do is make it read and rewrite all of its data into a new shard. Aurora Limitless avoids that initial overhead of copying data to a new shard through Aurora's storage level CoW mechanism.
There are other issues with sharding your data such as expensive joins. Limitless addresses some of these issues through collocation. With collocation, you can place related tables on the same shard to make JOINs less expensive. Additionally, Limitless supports three different table types: sharded, reference, and standard tables so tables can be distributed across the shards in different ways.
Aurora Limitless sounds great! Where does Aurora DSQL come in? There are a couple of things:
- Limitless cannot scale down to 0. It is not truly serverless
- Limitless doesn't support active-active multi-region writes
- Limitless still exposes sharding decisions to the customer. DSQL hides that partitioning from the client
Aurora DSQL
This leads us to the final evolution of Aurora: Aurora DSQL. It is easier to understand DSQL if you understand the motivation behind it. In Marc Brooker's words, their "goal was to build a relational database system that simplifies the work of application building and operations, freeing builders from worrying about scale, reliability, durability, and even multi-region fault tolerance."
DSQL achieves this with a fully disaggregated, serverless architecture that supports active-active multi-region writes. It also maintains strong consistency and remains compatible with Postgres. There's a lot to break down, but here is an animation to give you a better picture:
The first thing you might notice is that DSQL is even more disaggregated than Limitless. Unlike Limitless, where the DB is organized around routers and Postgres shards, DSQL abstracts those resources away from the customer entirely. Customers don't have to worry about choosing a shard key, thinking about table collocation, or when to shard (although Limitless also offers auto-sharding) with DSQL.
Another major difference in DSQL is the use of Optimistic Concurrency Control, or OCC, rather than relying on Postgres-style locking to prevent write conflicts. The basic idea behind OCC is that conflicts are checked at commit time rather than preventing conflicting work up front with locks. If conflicts are rare, then OCC works really well because transactions can proceed without waiting on one another. If contention is high, however, you will see many transactions rolling back and retrying.
Because we're already talking about concurrency control, another interesting part of DSQL is its implementation of MVCC. Like Postgres, DSQL can keep multiple versions of a row so transactions can read from a consistent snapshot. Instead of transaction IDs, DSQL uses timestamps to determine which versions of a row are visible to a transaction. When a transaction begins, it gets a timestamp that defines its snapshot, and it only sees row versions that were committed before that point in time.
In distributed systems 101, you're taught that you shouldn't rely on physical clocks because they can drift, but DSQL gets around this by using tightly synchronized physical clocks with known error bounds. Relying on physical clocks isn't unique to DSQL though, Limitless also uses timestamps for its MVCC. The difference here is that DSQL abstracts garbage collection away from users, while Limitless retains Postgres's VACUUM/AUTOVACUUM interface.
Lastly, DSQL was designed for active-active multi-region writes while still providing strong consistency. Basically, clients can issue writes to DSQL from multiple regions and once a write is committed, all subsequent transactions will see the newest state.
Summary
So to answer the question about why there are so many Auroras: they're all different databases designed to solve different problems. I'm still not sure why they're all named Aurora though. I think it's confusing, but the Aurora name also carries some credibility, which might be why Amazon decided to keep it.
Here's a comparison of all of them side-to-side:
| Area | Classic Aurora | Aurora Limitless | Aurora DSQL |
|---|---|---|---|
| Architecture | Single writer with scalable read replicas | Routers coordinate work across Postgres shards | Fully disaggregated and hides its underlying resources |
| Partitioning | No customer-managed sharding in this model | Hash-based sharding with customer-visible shard keys, collocation, and table types | Partitioning is hidden from the customer |
| Write Scaling | Writer only scales vertically | Cannot scale down to zero | Fully serverless |
| Multi-region writes | Not supported | Not supported | Supported with strong consistency |
| Concurrency control | Postgres-style | Postgres-style with timestamp-based MVCC | Optimistic concurrency control |
| Postgres compat | High | High with some limitless-specific restrictions | Postgres compatible, but not full feature parity (no pg extensions, only repeatable read isolation level, etc.) |
Reflection
This is more of a personal reflection that I had while reading this paper, but I recently saw a tweet by James Cowling, the CTO of Convex, that really resonated with me:
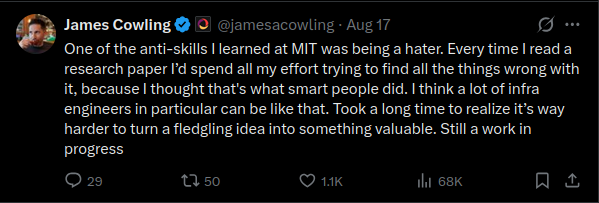
Reading these papers, I noticed that, subconsciously, I was trying to poke holes in the system and its design. Reading this tweet, I was just reminded that an immense amount of time and thought went into the making of each of these databases, and the folks at AWS don't need me to tell them about the tradeoffs of their system.
Thanks for reading!
edit:
After posting this article, it looks like someone working on these actual systems commented with the following clarification. I thought it would be helpful to include here:
"
I just want to add a simple clarification that might help with all of the Aurora product "family" confusion.
Aurora MySQL/Postgres is Aurora (or OG Aurora, if you like). It is one team and one technology. Postgres was added after MySQL, but is the same storage system and page writer underneath adapted for Postgres.
Aurora Limitless is from some other AWS group and the paper does not have anyone from the original Aurora team on it. They added higher-level routing and sharding on top of Aurora's storage system.
Aurora DSQL has nothing to do with original Aurora and no original Aurora contributors were involved.
"
-- one of the co-creators of the original Aurora system
(pretty amazing this article reached some of the folks actually working on all of these systems!)